Verifying the Linear Representation Hypothesis: How Interpretable Are Vision SAEs?
Teodor Chiaburu, Franz Motzkus, Frank Haußer, Felix Bießmann
Under Review
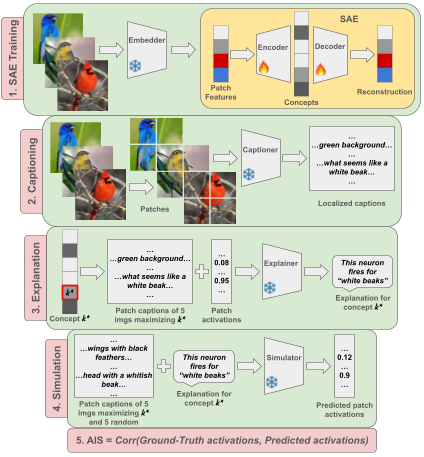
We adapt the Autointerpretability Score (AIS) - previously shown to align with human judgments in NLP - to vision tasks and validate our approach in a dedicated user study. We evaluate SAE concept quality using both standard metrics and our adapted AIS. We find that established interpretability metrics for SAEs correlate neither with one another nor with AIS, indicating that no single reference-free metric, whether grounded in the LRH or not, is sufficient for verifying the interpretability of vision SAEs. We argue these findings support recent calls for more verifiable, ground-truth-anchored design and evaluation of explanation methods. Download preprint here.